Understand SQL queries and improve them with execution plans
From the business list to an actual SQLite plan: testable hypotheses without universal performance promises.
An SQL query is not good merely because it looks short or happens to use an index. It must return the correct business information and fit the way the application is actually used. Only then does it make sense to assess the work the database performs. This guide follows a reviewable path from a result contract through an execution plan to a deliberately chosen composite index. A small PHP and SQLite example makes the decisions testable.
Define the result contract before optimizing
Our fictional application displays a selected customer's most recent open orders. The list contains no more than twenty entries and needs only an ID, creation time and amount. When creation times are equal, the higher ID comes first. That description is the result contract. It defines what must remain true after a technical change, independently of whichever execution strategy the database chooses.
In a real application, customer selection must come from an already checked authorization decision. Binding a parameter does not prevent someone from requesting another customer's records. Query construction and access control are different responsibilities. Our function explicitly receives the customer ID as an argument and does not claim to implement authentication or complete tenant isolation. The caller remains responsible for supplying a permitted selection.
Write two or three counterexamples before changing the query. A closed order belonging to the same customer must not appear. An open order belonging to another customer must not appear either. Two orders sharing a timestamp must not swap unpredictably. These business properties are more useful when verifying a change than merely comparing the number of rows returned.
The learning example's data model
The small table uses integer timestamps measured in seconds and integer amounts measured in cents. This keeps comparisons unambiguous within the example. A real application also needs deliberate choices about time zones, currencies and valid status transitions. An index does not resolve those questions. For our investigation, the following columns and explicitly invented orders are sufficient.
CREATE TABLE orders (
    id INTEGER PRIMARY KEY,
    customer_id INTEGER NOT NULL,
    status TEXT NOT NULL,
    created_at INTEGER NOT NULL,
    total_cents INTEGER NOT NULL
);
The ID identifies an individual order. The customer identifier associates it with a person or organization. Status restricts the required subset. Creation time together with ID defines the order of results. The amount is returned but controls neither selection nor sorting in this workflow. Those different roles provide the rationale for deciding which columns belong in the proposed index.
A name such as total_cents documents the unit and prevents some display misunderstandings. It does not establish that every stored amount was calculated correctly. When diagnosing a real application, check implausible values and missing business constraints before concentrating exclusively on speed. Efficiently returning incorrect information does not meet the result contract.
Express the query clearly first
SELECT id, created_at, total_cents
FROM orders
WHERE customer_id = :customer_id
  AND status = :status
ORDER BY created_at DESC, id DESC
LIMIT 20;
The WHERE conditions jointly describe the desired subset. ORDER BY defines its sequence and LIMIT bounds the output. The explicit column list shows which information the interface actually needs. It also prevents an internal notes field added later from automatically being returned to every existing consumer. This makes the query's output a more deliberate interface between storage and application code.
The second sorting column is intentional. Several orders may share the same second as their creation time. Without an additional unique key, their relative order has not been specified. A different plan can then appear to change the result when it merely exposes a previously undefined sequence. Do not confuse that situation with database corruption or assume that an incidental previous order was guaranteed.
Avoid reading SQL as an imperative program describing one fixed sequence of operations line by line. The database can choose different access paths while preserving the declared meaning. Our job is to express that meaning clearly and then examine the chosen implementation. Changing a query should make both the intended result and the technical hypothesis understandable to another reviewer.
Match each observation to its question
| Observation | Helps establish | Does not establish alone |
|---|---|---|
| Result comparison | Business equivalence and ordering | Good performance under load |
| Execution plan | Access path and sorting operations | Business value of a change |
| Repeated measurement | Behaviour under stated conditions | Identical behaviour on every installation |
| Application observation | Frequency and overall effect | Cause without further investigation |
Keep these forms of evidence separate. A plan can explain why a particular strategy is plausible. A timing measurement describes what happened during a particular execution. A moderately expensive query run repeatedly may matter more to the application than a very slow administrative operation used rarely. Choosing the right problem is therefore part of optimization rather than something that happens before the real work begins.
Use the plan to test a concrete hypothesis
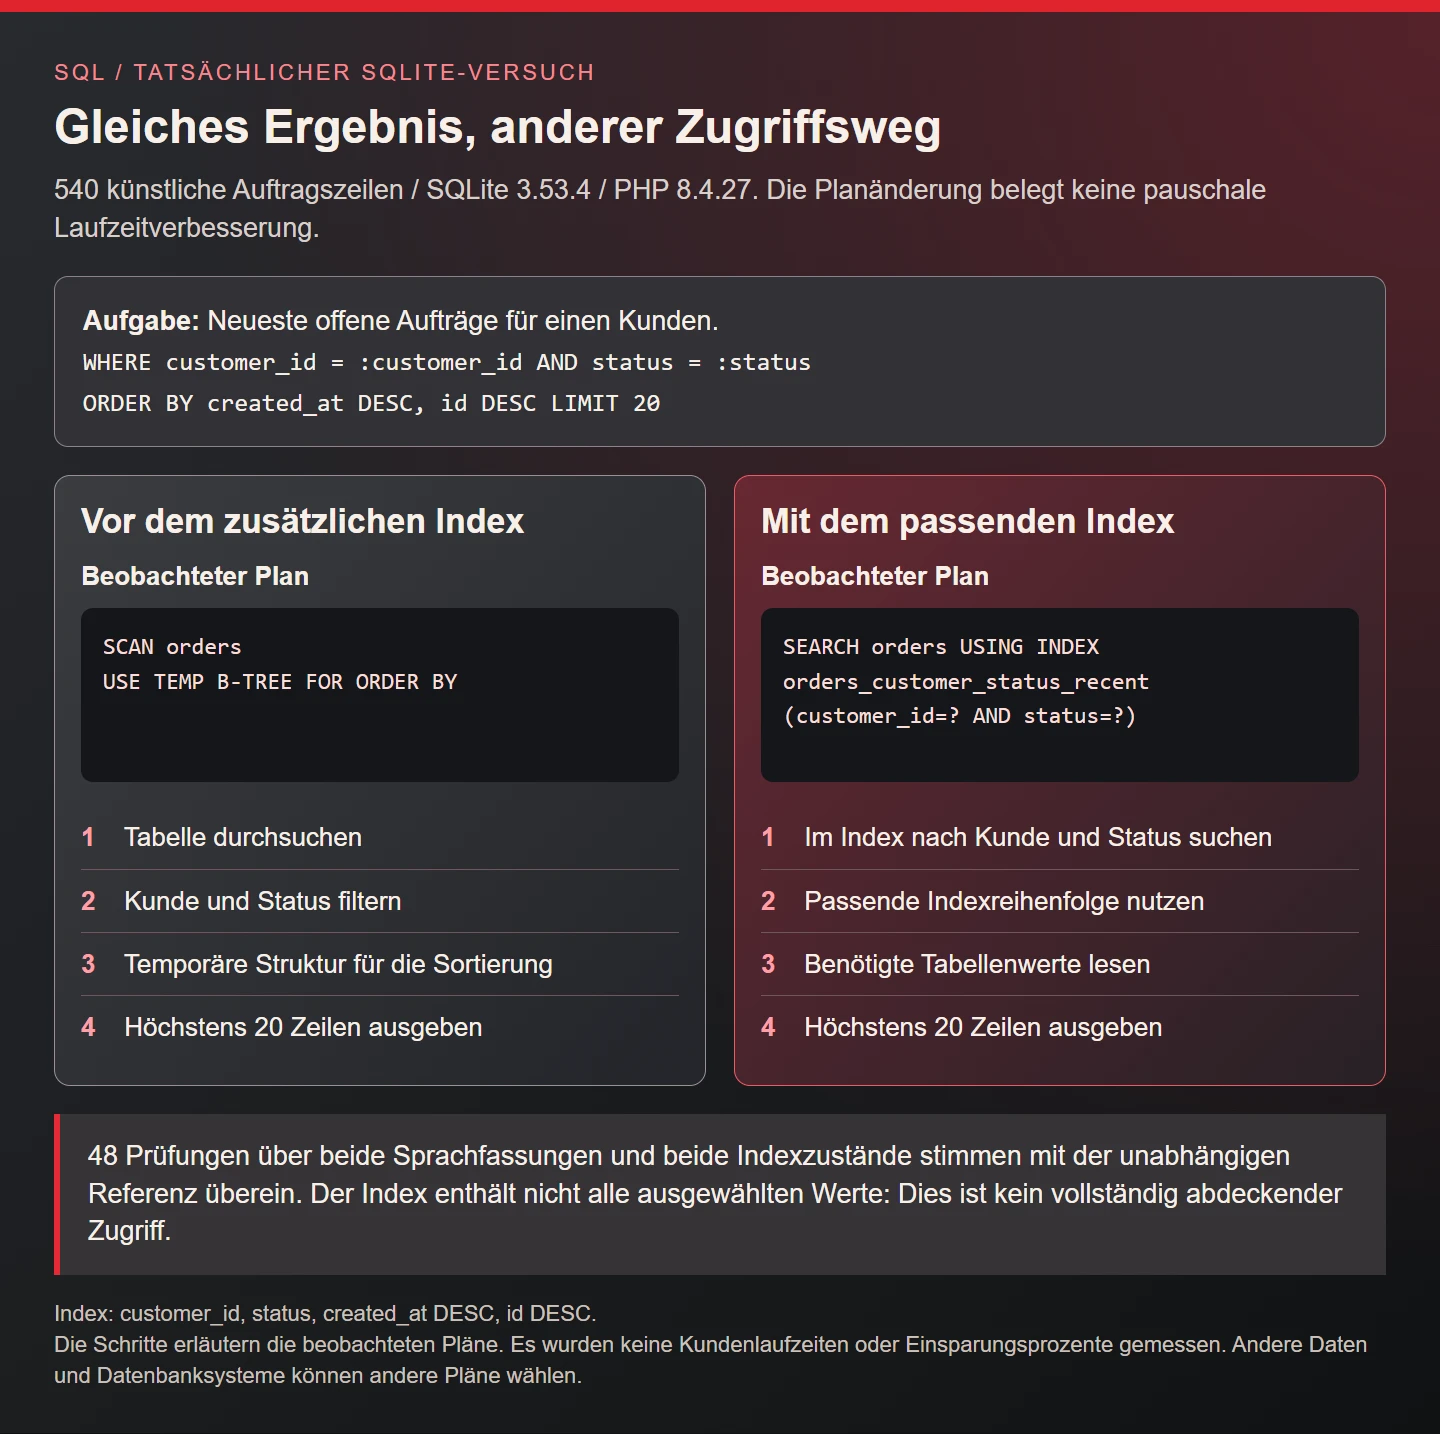
SQLite provides EXPLAIN QUERY PLAN. Our example examines the same SELECT with the same bound values. Relevant observations include whether the table is scanned, whether a particular index supports selection and whether an additional temporary sorting structure is used. The documentation warns that the exact textual output is not a permanently stable application interface.
The artificial test database is queried first without the additional index. Only that index is then created and the same query is executed again. The result and its ordering must remain identical. Changing one thing makes the connection reviewable. If the schema, conditions and sorting were all changed together, a different observation would be much harder to attribute to a particular cause.
A full table scan is not automatically a defect. When a table is small or a large proportion of its rows is needed, scanning can be reasonable. Ask which work is avoidable for this particular access pattern. Seeing any index name in a plan is not a quality verdict. A useful diagnosis explains what the path does and why it fits the task.
Derive the composite index from the task
CREATE INDEX orders_customer_status_recent
ON orders (customer_id, status, created_at DESC, id DESC);
The first two columns correspond to equality conditions. Within that combination, the remaining columns follow the requested result order. This is a reasoned hypothesis for our fixed list access. The SQLite query-planning documentation explains multicolumn indexes and the relationship between searching and sorting.
The rationale is more precise than “put the most important column first.” Customer, status and ordering together form the access pattern. A global list of every open order is a different pattern. It might need another index or work adequately using another strategy. Review the important queries together before giving each its own nearly identical index and increasing maintenance costs throughout the application.
The PostgreSQL multicolumn-index documentation also explains the significance of leading columns in B-tree indexes. This does not establish a cross-system rule that later columns can never be useful without a leading condition. Optimizers have additional strategies. Read the actual plan produced by your system with your data before deciding what an index can or cannot do.
Interpret the small experiment appropriately
The article's checking procedure compares actual SQLite plans before and after the index is created. It also calculates the expected list independently from the invented input rows. Consequently, two SQL runs cannot pass simply by agreeing on the same wrong result. The checks explicitly examine customer selection, status, the output limit and ordering, including equal creation times.
Observing a different access path does not establish an invented speed improvement. No percentage gain was measured for a customer application. A short in-memory example does not reproduce disk access, concurrent users or growth in a production dataset. Its value is that the technical hypothesis is tested in a way that another developer can inspect and repeat.
For your own investigation, retain the query, parameter class, schema, relevant indexes and plan together. Otherwise it becomes difficult to tell whether an apparent regression arose from changed data, a new filter or another database version. A comparison requires a described context. Preserve useful evidence rather than only the favourable line from one diagnostic output.
Use PDO parameters for values
The following function implements the query in PHP. It expects a prepared PDO connection with appropriate error handling. The query structure remains fixed while the two values are bound. The PDO::prepare() manual explicitly distinguishes these value parameters from identifiers and arbitrary SQL fragments.
<?php
declare(strict_types=1);

function recentOrders(PDO $db, int $customerId, string $status): array
{
    $stmt = $db->prepare(
        'SELECT id, created_at, total_cents
         FROM orders
         WHERE customer_id = :customer_id
           AND status = :status
         ORDER BY created_at DESC, id DESC
         LIMIT 20'
    );
    $stmt->bindValue(':customer_id', $customerId, PDO::PARAM_INT);
    $stmt->bindValue(':status', $status, PDO::PARAM_STR);
    $stmt->execute();
    return $stmt->fetchAll(PDO::FETCH_ASSOC);
}
A placeholder therefore cannot simply stand for the name of a sorting column. If the interface offers several sort orders, map each allowed choice to a fixed known expression. Customer and status binding remain separate from that decision. Unchecked text inserted into ORDER BY would still be dynamically assembled SQL, even if the WHERE values were handled correctly.
The PDO prepared-statement documentation describes the security benefit of bound values while noting that other unsafe query fragments remain a concern. In this function, values are values and the program defines the structure. Authorization to query the selected customer must already have been established by the caller. That responsibility does not disappear when the database accepts the statement.
Improve filters without changing their meaning
For date ranges, inspect how time is actually represented. With our integer timestamps, a calendar month can be expressed using an inclusive lower boundary and an exclusive upper boundary. Calculate both boundaries in advance for the relevant business time zone. Selection then does not require first converting every row into a formatted month name.
This suggestion does not resolve daylight-saving or time-zone questions. A calendar month in a business time zone is a domain definition. Incorrect boundaries can make a technically index-friendly query return the wrong orders. Add specific examples at both boundaries and around relevant time changes where applicable. Correct comparison operators cannot repair incorrectly calculated boundary values.
The SQLite optimizer overview explains multiple strategies for conditions and indexes. Avoid blanket statements such as “a function always prevents every index.” Expression indexes and system-specific optimizations can change that assumption. Formulate a comparable alternative, verify its meaning and inspect its plan before claiming an improvement.
Recognize joins that multiply rows
If an order has several line items, joining to the line-item table can return the same order repeatedly. Adding DISTINCT afterwards may remove visible duplicates without establishing that the underlying query models the task correctly. If the requirement is merely to establish the existence of a matching item, an existence condition can express the intention more directly.
Aggregates make this particularly important. Another join to a second detail table can multiply rows and count amounts several times. Use a small manually understandable dataset to inspect how often each row exists before aggregation. Repairing the answer takes precedence over accelerating an incorrect sum. A favourable execution plan is no substitute for checking the business relationship.
Production diagnosis therefore needs the domain relationships as well as column names. A query using plausible fields can still contain the wrong join condition. Compare specific known cases and the expected number of related records before concluding that the problem is purely about indexes. A correct relationship should be explainable without relying on the database's output as its own proof.
Treat excessive query counts as an application problem
A page might load twenty orders and then request a customer name separately for each one. Every individual request may be quick. Their number and repeated application-to-database round trips can still create unnecessary work. Monitoring only the slowest individual SQL statement can miss this pattern completely. Look at how the interface obtains its complete set of information.
Investigate whether the required reference data can be loaded in an appropriate joint query or a targeted batch. Do not eagerly retrieve every relationship without a reason. A compact list may need neither all line-item descriptions nor the complete change history. The correct data volume follows the interface's task rather than the maximum capabilities of an object model.
Record query calls per page operation alongside individual duration. These are different measurements. When a change derives its benefit from removing repeated work, the evidence should explain both. This also helps distinguish a database access issue from rendering, network or application processing that happens around the query.
Plan pagination and deterministic ordering
LIMIT bounds the initial list. Many subsequent pages require a separate navigation decision. A large OFFSET can involve walking past and discarding many earlier entries. Whether that matters practically depends on data volume, the plan and actual use. A rarely visited administrative archive has different requirements from a continuously used operational stream.
One alternative continues after the last seen creation-time and ID pair. The continuation condition must match the descending order precisely. The unique pair removes ambiguity when timestamps are equal. However, continuation state must not replace authorization or the original customer condition. A cursor is not permission to access a different set of records.
Also decide what should happen when orders are inserted or changed between requests. Deterministic sorting does not by itself create an unchanging snapshot across several page visits. State the desired user experience before comparing navigation strategies only by speed. Otherwise an apparently faster implementation may quietly change which records people can encounter while working through the list.
Indexes have operating costs
An additional index occupies storage and must be maintained during relevant writes. For an infrequently used list, that cost may matter more than a small read improvement. Establish which operations are common, how much data changes and which existing indexes perform similar jobs. Read optimization should be assessed alongside the workload it adds elsewhere.
The example intentionally leaves total_cents outside the index. The query still obtains the amount from the table. A wider covering index would be another hypothesis with different costs. Do not implement it merely because “covering” sounds better. Limit the experiment and measure the effect that actually matters for this application's workload.
Building an index on a large production table is also a planned database change. Suitable procedures and possible locking differ by system. Design the migration, backup and rollback approach for the actual environment. A successful small SQLite command is not an operational authorization to apply the same step to a heavily used database server without further assessment.
Distinguish EXPLAIN from actual execution
PostgreSQL documents EXPLAIN and EXPLAIN ANALYZE separately. The ANALYZE form actually executes the investigated statement and adds runtime observations. That distinction matters especially for statements that modify data. Do not treat a diagnostic invocation as a consequence-free description when it performs actual changes.
MySQL 8.4 documents its EXPLAIN variants with their own supported formats and limitations. Do not transfer exact syntax or the meaning of output fields between systems without checking. Renaming columns in a SQLite plan cannot turn it into a measured PostgreSQL or MySQL plan.
Perform deeper experiments in a suitable environment. Representative distributions and parameters matter alongside total row count. One large customer and many small customers can produce the same table size with very different access characteristics. Include the parameter classes the application genuinely uses rather than evaluating only a conveniently small result.
A compact diagnosis matrix
| Symptom | First investigation | Possible next experiment |
|---|---|---|
| Incorrect total | Join multiplication and conditions | Clarify relationships before aggregation |
| Expensive sorted list | Conditions, ordering and plan | Evaluate a suitable composite index |
| Many short queries | Calls per interface operation | Investigate a targeted batch |
| Slow later pages | OFFSET and actual navigation | Compare a suitable continuation approach |
| Worsening writes | Existing indexes and changes | Assess unnecessary similar indexes |
This matrix provides orientation rather than an automatic diagnosis. Record the initial observation, expected business result and technical assumption being changed for each experiment. Even a rejected approach then remains useful because it answered a specific question. Avoid preserving only successful changes while losing the evidence that explains why alternatives were unsuitable.
Check the benefit after making the change
After a successful focused test, observe the intended workflow. Does the overview actually become available sooner, or is the perceived bottleneck in another component? An additional network request, large response or expensive rendering operation can obscure the benefit of improved SQL. That does not invalidate the database work, but it places the result in the complete page operation.
Before adoption, agree which business and technical conditions must continue to hold: correct results, appropriate access and acceptable writing costs. Maintain a way back if real usage contradicts an assumption. Optimization is a reviewable change, not a final verdict covering every future data distribution or every application feature that might later reuse the query.
Checklist for a reviewable improvement
- The result, conditions and unique ordering are described.
- Authorization is checked independently of parameter binding.
- The original query and representative values are retained.
- The plan is interpreted for the database system actually used.
- Each change tests an understandable hypothesis.
- Business counterexamples establish result equivalence.
- Measurements and plan observations remain distinct.
- Call frequency and overall effect are considered.
- Write costs, index construction and rollback are planned.
- The evidence names its environment and limits rather than promising universal percentage gains.
Frequently asked SQL optimization questions
Does every filtered column need a separate index? No. The conditions and ordering actually used together matter. Several individual indexes are not automatically equivalent to an appropriate composite index. Examine the specific plan and the workload before choosing an index arrangement.
Is SELECT * always wrong? An explicit selection makes our output understandable and bounded. That does not establish a universal prohibition. Assess the required information, coupling and transfer volume for the actual consumer rather than applying a slogan without context.
Can a better plan establish a fixed speed improvement? A changed access path supports a hypothesis. A defensible timing statement needs measurements under described conditions. This checked example promises no particular improvement for someone else's database or production application.