Balance AI cost, speed and output quality
Make task-specific decisions, account for cache categories correctly and separate arithmetic examples from measured model performance.
A low token price does not automatically make an AI workflow economical. An output may require several revisions, unnecessary tool calls or a professional review taking longer than the original task. Conversely, a slower process does not automatically produce better work. The relevant question is whether a specific task reaches an acceptable outcome within its quality, time and cost constraints. That question requires a workflow comparison rather than an isolated price comparison.
This guide develops a repeatable selection method instead of a universal model ranking. It connects acceptance criteria, timing and complete task costs. A small JavaScript calculator demonstrates separate accounting for text token classes. Its 93 checks were actually executed. The token quantities are explicitly chosen arithmetic inputs, not a model benchmark. Sources and the rate snapshot were checked on November 9, 2026. A real calculation must confirm the applicable tariff, context class and services again.
Define a usable outcome first
Start with the work someone must subsequently use. A summary may need to preserve particular claims and provide verifiable evidence. A draft may need to follow an established editorial voice. Generated code must satisfy specified behavior and counterexamples. Those tasks require different criteria. “The answer sounds good” is insufficient when the important failure only becomes visible during the next stage of work. Write down that stage before comparing configurations.
Separate mandatory requirements from negotiable properties. An invented source may disqualify an answer. A slightly verbose sentence may allow a small editorial correction. Combining both into one average lets a serious error be compensated by attractive style. Define disqualifying failures first. Only after minimum requirements pass should you compare readability, length or the effort needed for minor corrections. This ordering makes the business meaning of a result explicit.
| Task | Possible minimum requirement | Further comparison |
|---|---|---|
| Evidence-based summary | No unsupported central factual claim | Clarity and brevity |
| Form code | Specified inputs and counterexamples work | Maintainability and integration effort |
| Editorial draft | No invented product promises | Voice and revision effort |
| Classification | Allowed categories and defined handling of uncertainty | Time and cost per completed case |
The official OpenAI evaluation guidance discusses task-specific tests and calibrating automated assessment against human judgment. Those methodological ideas do not require one particular evaluation product. At the source date, the older Evals platform described on that page is already read-only and scheduled to shut down on November 30, 2026. Do not base a new integration solely on historical Evals API examples.
Build a small but informative task set
Select typical tasks from the intended workflow. Add difficult cases that expose consequential errors. A summary test might include conflicting statements or missing evidence. Extraction tests might include inconsistent spelling and absent fields. Record what counts as correct for each case and who reviewed that expectation. Otherwise the test may only measure agreement with an unverified reference answer. A polished reference can contain exactly the error the evaluation should detect.
Hold back an additional set that is not used for ongoing prompt adjustments. Otherwise a configuration can learn to satisfy familiar examples without handling new work reliably. Preserve original inputs, supplied context and outputs together. Comparing answers is weak evidence if one received substantially better source material. The same applies to additional tools, longer permitted processing and different output limits. Comparable conditions matter even when configurations intentionally use different internal methods.
A consistent task set does not require every case to occur equally often. Common routine cases and rare critical cases play different roles. Report both groups separately. A strong aggregate success rate can conceal repeated failure on precisely the unusual cases requiring care. Include the size of each group. A handful of successes does not support a precise claim about an entire business process, especially when the production distribution remains uncertain.
Measure speed across the complete workflow
In an interactive application, the first relevant question is when a person receives useful information. For an overnight batch, the important point may be when all checked results are available. These are different timestamps. Record the start, first genuinely useful output and complete finish separately. An early introductory sentence does not necessarily reduce time to a usable decision. A progress animation also does not accelerate a blocking tool operation.
The latency optimization documentation discusses fewer output tokens, fewer requests and parallel independent steps. None of these establishes a guaranteed response time for a specific application. Trace the actual workflow and find its slow section. A delayed data lookup, a queue and a long generated output need different changes. Only one of those necessarily concerns the model choice itself.
Repeat measurements under comparable conditions and retain every attempt. One quick run is not a dependable response-time estimate. Report sample size, variation and unusually slow cases. If reporting a percentile, state its calculation and the number of observations. With a small set, precise decimal places can imply more certainty than the evidence supports. A simple table containing all observed durations may provide a more honest account of the current evidence.
Parallel execution helps only where steps are genuinely independent. An answer checker cannot inspect a result that has not arrived. Two independent research tasks may run concurrently. Still bound concurrency and overall expenditure. More simultaneous calls can simply move a queue elsewhere. Include cancelled and subsequently discarded results in the accounting because work may already have been performed. Wall-clock improvement and reduced billed work are separate questions and should remain separately visible.
Calculate the cost of a completed task
Distinguish one model request from a completed assignment. An assignment may involve several attempts, external tools, retrieval and human revision. Record those components separately. An inexpensive call can become costly if it repeatedly causes additional loops. A higher unit price can be worthwhile if comparable observation shows sufficient avoided rework. That observation must come from the actual task. It cannot be inferred from a product name or a generic quality label.
The official cost optimization guide includes reducing requests and choosing a model size suited to the task. Treat these as changes to test. For example, remove demonstrably irrelevant context and repeat the same acceptance cases. A shorter context that omits essential evidence is not a successful optimization. Evaluate savings together with the outcome rather than recording a lower bill as the only result.
A useful total also needs a denominator: how many tasks reached an accepted outcome? Divide the evaluation block's total cost by that count. If no task was accepted, there is no meaningful finite average per success. Do not hide failed attempts by filtering the record to successful outputs. Capacity planning also needs the expenditure on unfinished tasks. Those costs already exist even though the work cannot yet be counted as completed success.
Assign tariffs and token classes correctly
The current API pricing table distinguishes model, processing mode, context class and multiple token categories. Our arithmetic uses the listed GPT-6.1 Sol Standard short-context text rates at the source date. This is not a recommendation of a quality level. The quantities below are deliberately selected inputs to a calculation. No corresponding model request was made or invoiced.
| Category | Illustrative quantity | USD per million tokens | USD contribution |
|---|---|---|---|
| Ordinary input | 600 | 2.00 | 0.001200 |
| Cache read | 400 | 0.10 | 0.000040 |
| Cache write, 30 minutes | 200 | 2.50 | 0.000500 |
| Cache write, 12 hours | 0 | 5.00 | 0.000000 |
| Output | 300 | 10.00 | 0.003000 |
Total input is 1,200 tokens. Cache reads and both write categories are included in that total, leaving 600 ordinary input tokens. The prompt caching documentation explains this separation. Charging all 1,200 at the ordinary input rate and then adding the special categories double-counts quantities. Treating every input token not read from cache as ordinary input would also miss the separately priced writes.
The example total is USD 0.004740. It excludes tools, other modalities, tax, currency conversion and additional task attempts. The cache quantities are not predicted: they must come from the actual usage information for the relevant response. Repeated wording alone does not guarantee a particular cache hit rate. Actual reconciliation needs the current interface, applicable rates and recorded quantities. Keep assumptions separate from observed usage rather than letting a calculator turn them into apparent facts.
A complete calculator with an explicit unit
The following function expects token counts as nonnegative safe integers. Rates are integer strings representing millionths of a US dollar per million tokens. An input rate of USD 2.00 is therefore stored as 2000000. Document the unit explicitly. A function name alone will not prevent mixing dollars, cents and millionths of dollars, particularly when a separate reporting system later consumes the result.
const TOKEN_KEYS = ['cachedInputTokens', 'cacheWrite30mTokens', 'cacheWrite12hTokens', 'inputTokens', 'outputTokens'].sort();
const RATE_KEYS = ['cachedInputMicrosPerMillion', 'cacheWrite30mMicrosPerMillion', 'cacheWrite12hMicrosPerMillion', 'inputMicrosPerMillion', 'outputMicrosPerMillion'].sort();
function exactKeys(value, keys) {
  return value && typeof value === 'object' && !Array.isArray(value) &&
    Object.keys(value).sort().join(',') === keys.join(',');
}
export function quoteTextUsage(usage, rates) {
  if (!exactKeys(usage, TOKEN_KEYS) || !exactKeys(rates, RATE_KEYS)) throw new TypeError('Ungültige Felder.');
  for (const key of TOKEN_KEYS) {
    if (!Number.isSafeInteger(usage[key]) || usage[key] < 0 || usage[key] > 1_000_000_000) throw new TypeError('Ungültige Tokenzahl.');
  }
  const specialInput = usage.cachedInputTokens + usage.cacheWrite30mTokens + usage.cacheWrite12hTokens;
  if (specialInput > usage.inputTokens) throw new TypeError('Cache übersteigt Eingabe.');
  for (const key of RATE_KEYS) {
    if (typeof rates[key] !== 'string' || !/^(0|[1-9][0-9]{0,12})$/.test(rates[key]) || BigInt(rates[key]) > 1_000_000_000_000n) {
      throw new TypeError('Ungültiger Satz.');
    }
  }
  const ordinary = BigInt(usage.inputTokens - specialInput);
  const parts = [
    [ordinary, rates.inputMicrosPerMillion],
    [BigInt(usage.cachedInputTokens), rates.cachedInputMicrosPerMillion],
    [BigInt(usage.cacheWrite30mTokens), rates.cacheWrite30mMicrosPerMillion],
    [BigInt(usage.cacheWrite12hTokens), rates.cacheWrite12hMicrosPerMillion],
    [BigInt(usage.outputTokens), rates.outputMicrosPerMillion]
  ];
  const numerator = 1000n * parts.reduce((sum, [tokens, rate]) => sum + tokens * BigInt(rate), 0n);
  const nanoUsd = (numerator + 999_999n) / 1_000_000n;
  return {nanoUsd: nanoUsd.toString(), usd: (nanoUsd / 1_000_000_000n).toString() + '.' +
    (nanoUsd % 1_000_000_000n).toString().padStart(9, '0')};
}
The arithmetic uses large integers and rounds the combined total upward once to a billionth of a US dollar. It does not claim identical rounding to a provider invoice. Its output is a quotation for the specified categories. Its own bounds constrain this example, not permissible API calls. Missing or additional fields are rejected so an unprocessed new cost category does not silently appear to be included in a complete calculation.
The result below was produced using that module. The complete fixture distinguishes its assumptions from measured properties. This calculation establishes neither model quality nor response speed. Those require the separate task and timing observations described earlier. The calculator is a limited component of an evaluation, not an automatic purchasing recommendation. Keeping the boundary visible makes it easier to discover missing information before using the output for a budget decision.
{
  "scope": "Illustrative token counts, not a measured model call or invoice. OpenAI GPT-6.1 Sol Standard short-context text rate snapshot checked2026-11-09. No additional services/taxes/currency conversion included.",
  "usage": {
    "inputTokens": 1200,
    "cachedInputTokens": 400,
    "cacheWrite30mTokens": 200,
    "cacheWrite12hTokens": 0,
    "outputTokens": 300
  },
  "rates": {
    "inputMicrosPerMillion": "2000000",
    "cachedInputMicrosPerMillion": "100000",
    "cacheWrite30mMicrosPerMillion": "2500000",
    "cacheWrite12hMicrosPerMillion": "5000000",
    "outputMicrosPerMillion": "10000000"
  },
  "partsUsd": {
    "ordinaryInput": "0.001200000",
    "cachedInput": "0.000040000",
    "write30m": "0.000500000",
    "write12h": "0.000000000",
    "output": "0.003000000"
  },
  "result": {
    "nanoUsd": "4740000",
    "usd": "0.004740000"
  },
  "ordinaryOnlyResult": {
    "nanoUsd": "5400000",
    "usd": "0.005400000"
  }
}
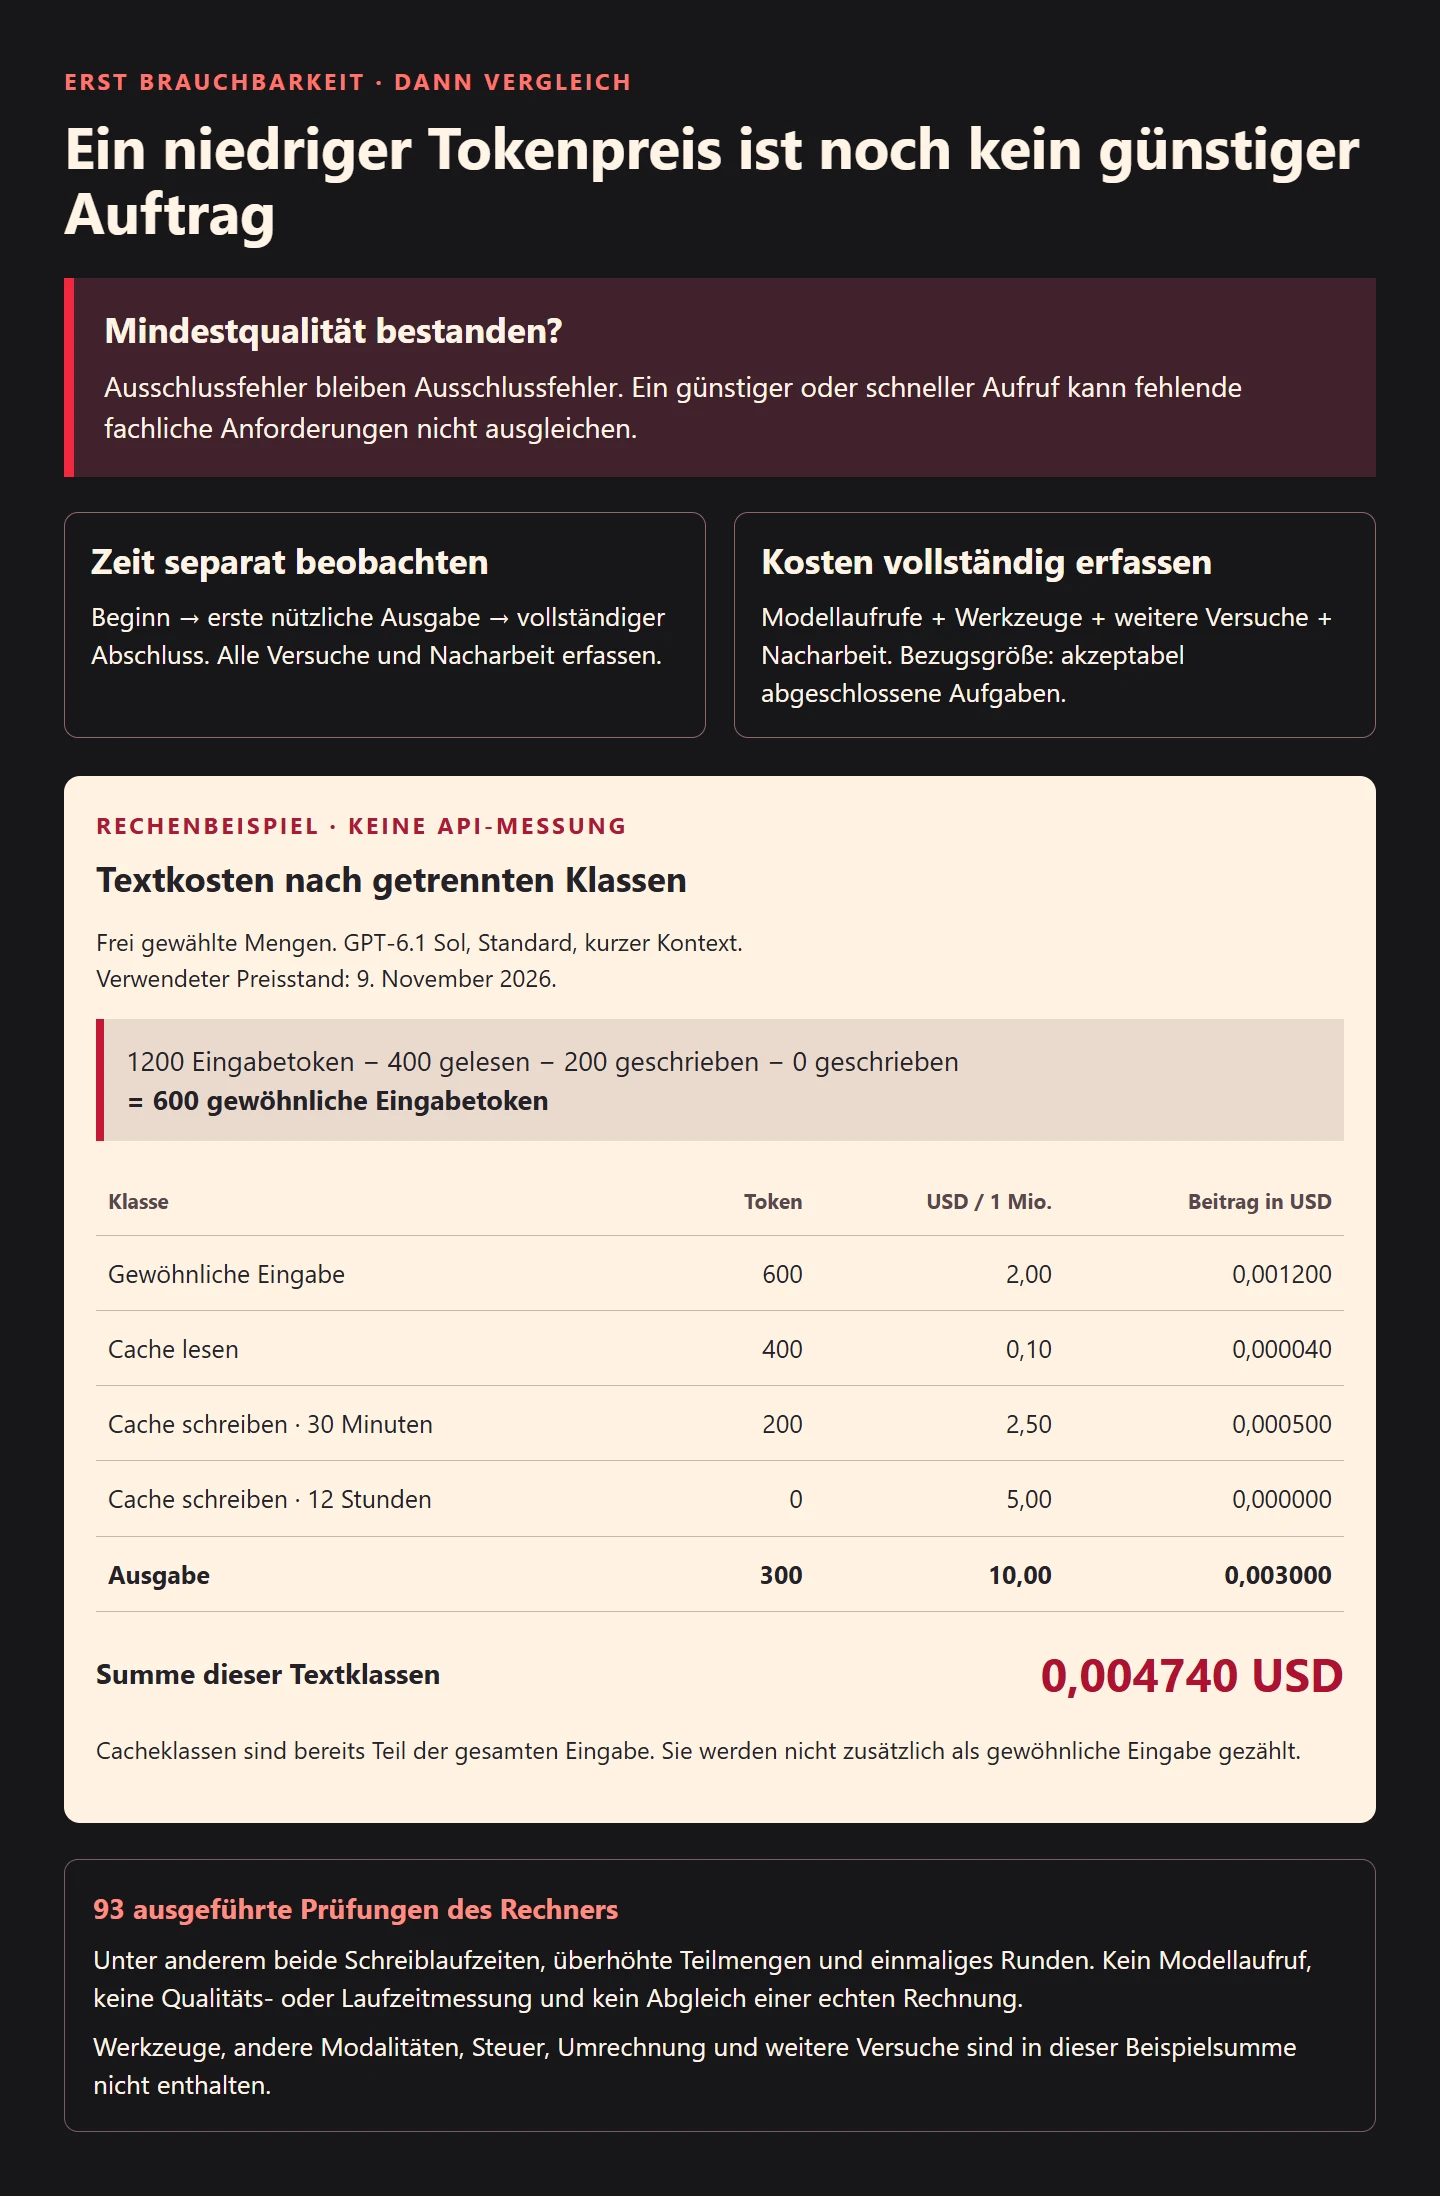
What the 93 executed checks cover
The check run verifies the example sum, completely cached input, both write lifetimes and ordinary input without caching. Counterexamples cover negative values, fractional token counts, missing properties and invalid strings for rates. The sum of special input categories must not exceed total input. Additional checks cover large integers and rounding the combined sum once. Inputs must remain unchanged so a repeated calculation does not accidentally use modified quantities.
All 93 conditions ran without a model call. They establish calculator behavior for the tested cases. They do not establish that a provider usage response was mapped correctly into this contract or that every item on a real invoice has been included. That integration needs further counterexamples with actual usage fields and reconciliation against billing. A correct arithmetic function can otherwise conceal incomplete collection. Treat the parser, rate configuration and reporting layer as additional components requiring evidence.
Decide without a misleading universal score
Filter configurations through mandatory requirements first. Compare quality, completed-task cost and elapsed time separately among the remaining options. One option is especially interesting when it is no worse on every relevant criterion and better on at least one. Often genuine tradeoffs remain. Then the use case decides: an interactive helper and an extensive overnight analysis do not need identical weighting. Record that weighting before interpreting a convenient winner.
Write the conclusion as a bounded statement: this configuration meets these requirements on this task set under the observed conditions. Avoid a universal ranking for unrelated tasks. Also define when another route takes over. Escalation can make sense when evidence is missing or a functional test fails. Confident wording from a model is not a reliable reason to skip a check. The triggering condition should be tied to observable task requirements.
If simple cases should use a less expensive configuration, the routing mechanism needs testing too. “Simple” needs an operational definition. Incorrect routing can erase the benefit of the entire strategy. Evaluate the complete chain, including recognition, retries and final acceptance. Measuring only the least expensive stage captures one part of the future workflow. Include the cost of discovering that a case requires escalation, not only the request that eventually succeeds.
Human revision requires the same care. Record what was corrected, the time spent and whether the original task could then be accepted. A quick stylistic adjustment differs from redoing the factual research. Avoid reducing both to an undifferentiated edit count. The record should make clear whether a configuration produces usable drafts or merely plausible starting material. These can both have value but support different claims about saved effort.
A checklist for a defensible comparison
A short review scale can support collaboration if its levels describe actual usability. One possible editorial scale has four states: unusable, requiring substantial rework, usable after targeted correction and immediately usable under the stated requirements. Add a reviewed example from your own task set for each state. The labels organize judgments. They do not replace specific failure descriptions or override disqualifying conditions established before testing.
| Level | Usability for the specified task | Evidence to retain |
|---|---|---|
| 0 | Unusable | Missing core or disqualifying failure |
| 1 | Substantial rework required | Essential work still missing |
| 2 | Usable after targeted correction | Specific change and effort |
| 3 | Immediately usable under the requirements | Checks actually passed |
This is an editorial proposal, not a universal model standard. Reviewers should first assess the same outputs independently and discuss disagreements. If one person treats a missing source as a small edit while another sees a fundamental failure, clarify the requirement. Averaging the incompatible judgments does not resolve their underlying difference. Keep the original judgments alongside any later agreed conclusion.
Where practical, hide the producing configuration during quality review and vary output order. Product reputation and expected price can influence an assessment. Record actual changes during revision rather than a single edited flag. Correcting sentence structure differs from researching missing evidence or replacing an algorithm. Also record whether the revised output was accepted. Time spent on an output that remains unusable is expenditure without a completed success.
Finally, compare equivalent operating conditions. One idle request and a saturated concurrent batch do not provide a clean model-speed comparison. Record concurrency and distinguish controlled technical observations from later production behavior. Preserve the previous configuration and define a practical rollback trigger. A version, responsible reviewer and observable failure condition can be sufficient for a small workflow. They make a later deterioration attributable instead of leaving the team with an unexplained impression.
- Describe the task and acceptable final outcome concretely.
- Define disqualifying failures before scoring softer properties.
- Document typical and critical task groups separately.
- Preserve context, model identifier, settings and tool access.
- Measure first useful output and complete finish separately.
- Include all attempts and required revision.
- Check tariff date, units and every applicable cost category.
- Account for cache reads and writes without double-counting.
- Calibrate automated assessments against professional judgment.
- Repeat relevant tests after a material change.
Retain rejected configurations as well. A later price change can alter an economic decision without changing task suitability. A changed model or context strategy can affect outcomes while the price remains unchanged. Both require appropriate renewed evidence. Cost, speed and quality can be balanced usefully when every number belongs to a defined task and an inspectable record. That record turns an attractive demonstration into a decision someone can review and revise.