Develop search, filtering and pagination together
Select all matches, order them consistently and keep them reachable through dependable page links.
Search, filters and page form one shared state
A result list becomes predictable when query, category, ordering and page are treated together. A useful filter combined with an old page number can produce an apparently empty list. A changed order that loses the selected category feels broken. We therefore develop these four values as one understandable state rather than independent controls with disconnected side effects and assumptions about what happened previously.
Our complete example searches twelve explicitly fictional records in website, app and AI categories. Three results fit on each page. This small dataset makes every decision inspectable: which records match, how they are ordered and which are actually displayed? An original Node server renders the HTML response. No browser JavaScript is required for searching, selecting a category or changing result pages.
The URL describes the current selection. Someone can reopen it, copy it and return through normal browser history. A GET form changes the selection, while ordinary links move between pages. This deliberately simple foundation establishes a clear contract. Any later dynamic enhancement should preserve the same meaning for query and page rather than quietly introducing another competing interpretation.
Begin with a deliberately bounded search contract
First decide what the search actually promises. This example searches only title and summary. Every word separated by spaces must occur, although one may occur in the title and another in the summary. Category selection adds another condition. The resulting intersection is easy to explain and can be verified against individual fictional records instead of an opaque external ranking service.
There is no automatic spelling correction, synonym dictionary or language-model interpretation. The unaccented German prufen does not automatically match prüfen. Related grammatical forms are not reduced to a shared stem. Such additions can be useful, but each needs its own rules and examples. Interface wording should not create broader expectations than the implemented algorithm can actually fulfil for the intended content.
Punctuation remains literal. A dot and an asterisk are not executed as a regular expression. Nor does this design build a SQL statement from input, because it processes a small array. A future database integration must preserve the intended matching meaning using bound parameters and suitable queries. This example is neither a full-text index nor evidence of performance on a large production catalogue.
Read and validate input consistently
The parser accepts exactly four parameter names. Unknown names and repeated values are rejected. Category and order use explicit allowlists. Page must be a positive decimal integer of at most four digits. Zero, negative values, fractions and leading-zero spellings are outside the contract. The server responds to such invalid input with an appropriate error status instead of silently pretending it received a different request.
The query is normalised to NFC. Outer whitespace is removed and repeated internal spaces are collapsed. Control characters are rejected before this normalisation. The resulting value may contain at most 80 Unicode code points. This is an application-specific input boundary, not a claim about visible character widths or a universal search-engine rule. One visible combined character can consist of several code points.
Missing or empty optional values use the documented defaults. That decision is tested alongside rejection cases. Repeated parameters do not leave a library or framework to choose an accidental winner: the example rejects repetition explicitly. Another contract is possible, but parser, interface and evidence must agree on it. Clear rules matter more than a superficially convenient interpretation that changes between layers.
MDN: URLSearchParams · Unicode Normalization
Filter first, order second and paginate last
Processing order is essential. First determine every matching record. Then sort that entire selection. Only afterwards take the slice for the requested page. Cutting three arbitrary records first and filtering them afterwards could overlook matches elsewhere in the collection. It would also prevent the displayed total from accurately describing the complete selection. Counting and slicing must refer to the same underlying result set.
Newest-first ordering compares the date and then the unique ID. Title ordering uses a German Intl.Collator followed by the same ID tie-breaker. Equal dates or titles consequently still have a defined order. The fixtures have fixed values. Filtering creates a new selection before sorting, so a search does not mutate the order of the original dataset used by subsequent requests.
A deterministic order supports understandable pages but cannot prevent every change in a live collection. New records arriving between two requests can shift an offset-based page. Large or frequently changing collections may need another pagination strategy. That choice depends on dataset size, rate of change and the visitor’s actual task. It should follow observed requirements rather than being inferred from this intentionally tiny example.
Show the complete independently testable search core
The following module contains the twelve records, input parsing, selection and query-string construction. It can run independently of HTTP presentation. We can therefore check an intersection of search term and category directly without imitating a browser click. The visible interface then uses exactly that same core instead of a second search implementation that merely appears to follow similar rules.
Page size is fixed at three. An empty result set has one empty display page. A correctly formed page number beyond the available range is bounded to the final existing page. This differs from an invalidly written page number. The server deliberately handles those situations differently and subsequently exposes the state actually used in the address, keeping the document and URL in agreement.
export const records = [
  ['01','Webseiten planen','web','2026-02-01','Ziele und Inhalte einer Webseite abstimmen.'],
  ['02','Webseiten pflegen','web','2026-02-02','Regelmäßige Pflege und klare Zuständigkeit.'],
  ['03','Webseiten testen','web','2026-02-03','Bedienung und Inhalt einer Webseite prüfen.'],
  ['04','Webseiten gestalten','web','2026-02-04','Typografie und Hierarchie sinnvoll entwickeln.'],
  ['05','Apps planen','app','2026-02-05','Aufgaben und mobile Wege beschreiben.'],
  ['06','Apps offline nutzen','app','2026-02-06','Entwürfe auf dem Gerät erhalten.'],
  ['07','Apps veröffentlichen','app','2026-02-07','Eine Freigabe nachvollziehbar vorbereiten.'],
  ['08','Apps prüfen','app','2026-02-08','Mobile Bedienwege wiederholt testen.'],
  ['09','KI einsetzen','ki','2026-02-09','Konkrete Aufgaben und Grenzen benennen.'],
  ['10','KI prüfen','ki','2026-02-10','Ergebnisse anhand von Quellen prüfen.'],
  ['11','KI automatisieren','ki','2026-02-11','Einen klar begrenzten Ablauf abstimmen.'],
  ['12','KI dokumentieren','ki','2026-02-12','Entscheidungen und Quellen erhalten.']
].map(([id,title,category,date,summary])=>({id,title,category,date,summary}));
const allowed = new Set(['q','category','sort','page']);
const categories = new Set(['all','web','app','ki']);
const sorts = new Set(['newest','title']);
const collator = new Intl.Collator('de', {sensitivity:'base', numeric:true});
const fold = text => text.normalize('NFC').toLocaleLowerCase('de');
export function readQuery(params) {
  for (const key of params.keys()) {
    if (!allowed.has(key) || params.getAll(key).length !== 1)
      throw new Error('Unzulässiger oder mehrfacher Parameter.');
  }
  const raw = params.get('q') || '';
  if (/[\u0000-\u001f\u007f]/u.test(raw)) throw new Error('Suchbegriff enthält Steuerzeichen.');
  const q = raw.normalize('NFC').trim().replace(/\s+/gu,' ');
  if (Array.from(q).length > 80) throw new Error('Suchbegriff ist zu lang.');
  const category = params.get('category') || 'all';
  const sort = params.get('sort') || 'newest';
  const rawPage = params.get('page') || '1';
  if (!categories.has(category) || !sorts.has(sort) || !/^[1-9][0-9]{0,3}$/.test(rawPage))
    throw new Error('Filter, Sortierung oder Seite ist ungültig.');
  return {q, category, sort, page:Number(rawPage)};
}
export function findRecords(state, source=records) {
  const words = fold(state.q).split(' ').filter(Boolean);
  const filtered = source.filter(row => (state.category === 'all' || row.category === state.category)
    && words.every(word => fold(row.title + ' ' + row.summary).includes(word)));
  filtered.sort((a,b) => (state.sort === 'title' ? collator.compare(a.title,b.title)
    : b.date.localeCompare(a.date)) || a.id.localeCompare(b.id));
  const pages = Math.max(1, Math.ceil(filtered.length / 3));
  const page = Math.min(state.page, pages);
  return {state:{...state,page}, total:filtered.length, pages,
    rows:filtered.slice((page-1)*3,page*3)};
}
export function queryString(state) {
  const p = new URLSearchParams();
  if (state.q) p.set('q',state.q);
  if (state.category !== 'all') p.set('category',state.category);
  if (state.sort !== 'newest') p.set('sort',state.sort);
  if (state.page !== 1) p.set('page',String(state.page));
  return p.size ? '?' + p.toString() : '';
}
A changed selection starts on page one
The GET form includes query, category and ordering, but no hidden field for the current page. Changing any of those controls and activating Search therefore starts on page one. This small detail prevents a familiar failure: someone is on a late page and then narrows the selection to only a few results. The previous page number must not silently continue governing the new selection.
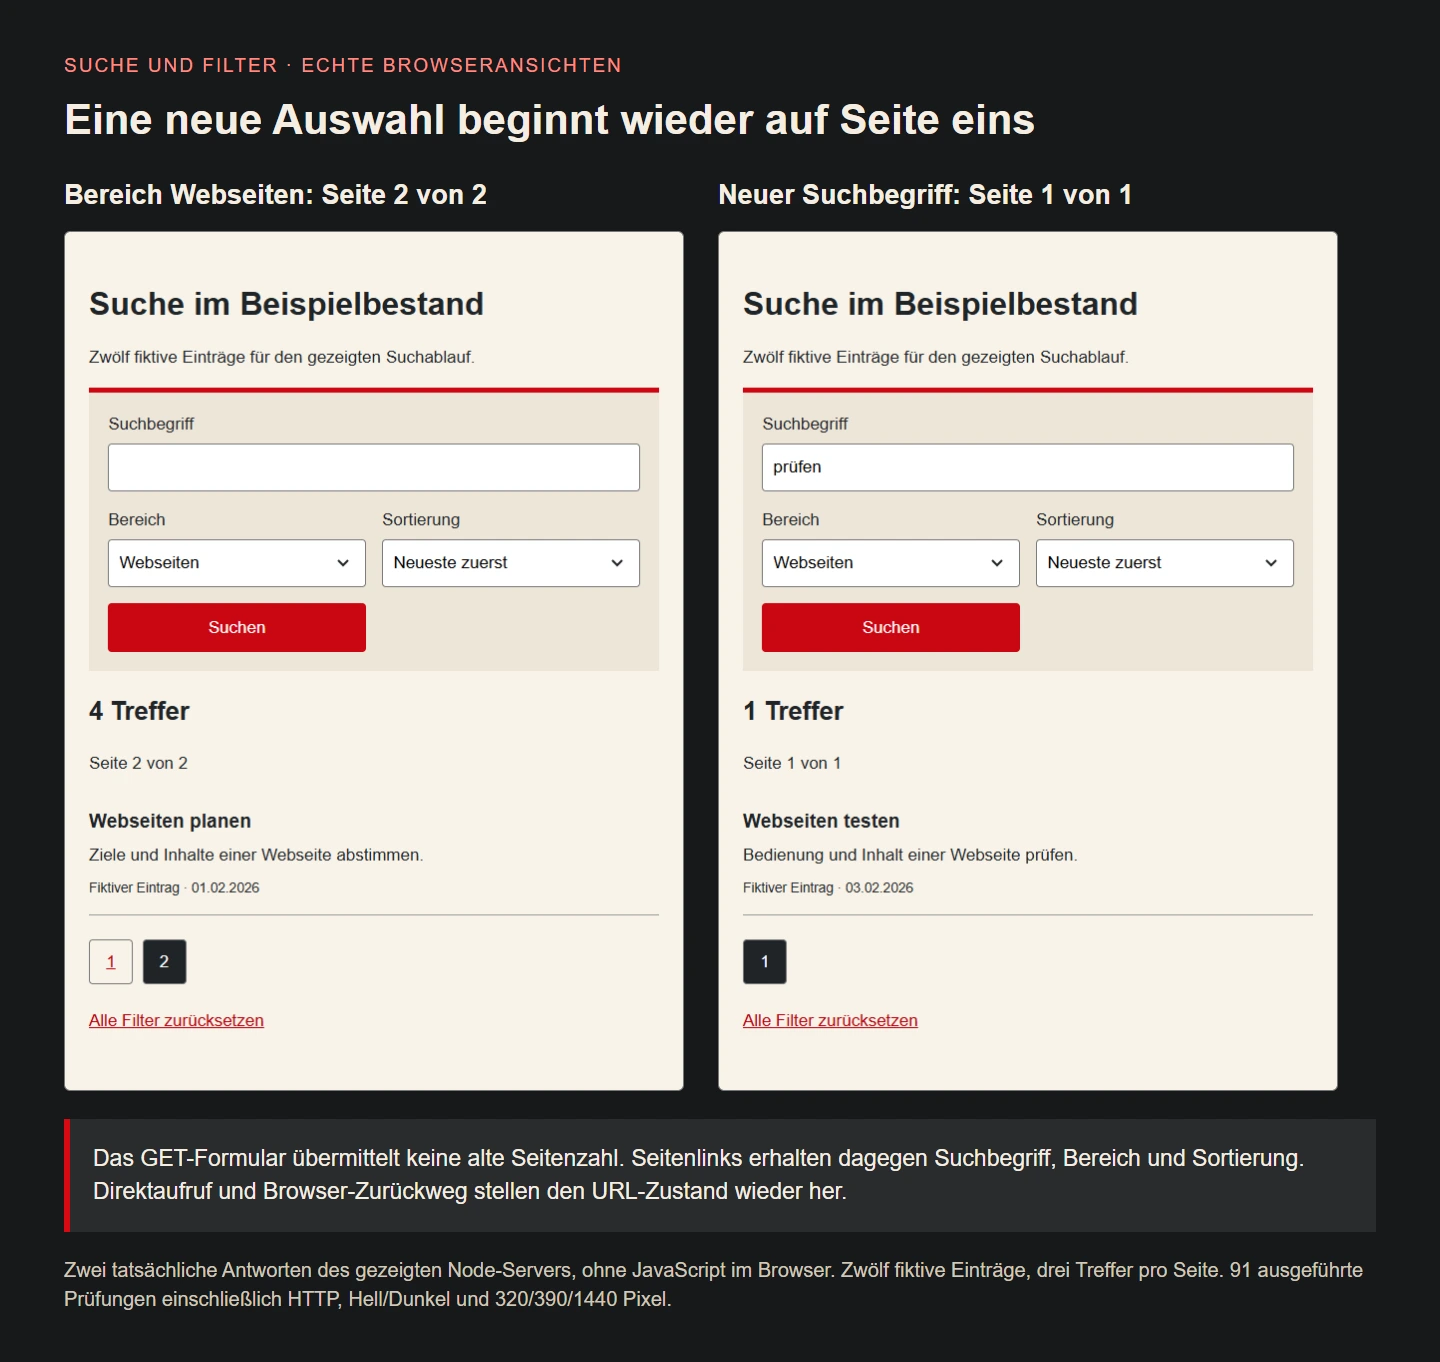
The actual browser journey first opens page three of the whole collection. Choosing the website category then produces page one of two. An ordinary page link reaches the second page while preserving that category. Searching for the German word prüfen within the same category subsequently returns exactly one record on the first and only result page. The screenshots show the latter transition directly.
Changing order follows the same form rule. A different order is a new view of the selection and starts at its beginning. The server does not have to guess which document was previously visible because the request explicitly describes the new state. Meanwhile, ordinary browser history still provides a route back to the previous selection and page when someone wants to return.
Page links preserve the complete selection
Each page link is constructed from the complete current state and changes only the page number. Query, category and ordering remain present. URLSearchParams builds the address rather than unchecked string concatenation of individual user values. Output into an HTML attribute is separately escaped for that context. URL encoding and HTML escaping solve different problems, so one does not replace the other in the template.
Defaults are omitted from the normalised address. Page one needs no explicit page parameter. All categories and newest-first ordering likewise need not appear in every link. This shortens addresses and removes unnecessary spellings of the same simple state. It is an application normalisation rule, not by itself an indexing strategy, a canonical policy for every search variant or any promise of improved rankings.
The current page is explicitly identified in navigation, while the others remain ordinary links. The tiny collection can show all four possible pages. A large catalogue needs a sensible bounded page range or another navigation strategy. Generating thousands of links simply because a page count is available would not be a useful extension of this implementation. Navigation should still serve the visitor’s next action.
Distinguish invalid requests from a valid empty selection
An invalid page value is not a search result. Here it produces status 400 and a clear reset action. A valid query with no matches instead produces status 200 and an explicit empty state. These situations need different explanations. Otherwise someone cannot tell whether the request was technically rejected or genuinely matched nothing under the stated rules and selected category.
A positive page beyond the selection is correctly formed but unavailable in the current result set. This example temporarily redirects to the last matching page while retaining the other values. If nothing matches, page one is used. A temporary redirect avoids claiming that a page unavailable today could never exist after later changes to the underlying collection or the visitor’s selected search terms.
Another catalogue can deliberately choose a different response contract. What matters is agreement between address, output and feedback. This design applies its own rules consistently and tests actual HTTP responses. Invalid input is not concealed behind an apparently successful default list that silently ignores what someone requested. Predictable failure is part of a useful search interface, not a separate finishing detail.
Connect HTTP behaviour to the rendered document
The server accepts GET on the explicitly defined search path. Other paths receive 404, and an unsupported method receives 405 with the allowed method identified. Valid requests use the shared parser and search module. A different normalised address causes a temporary redirect. Only the resulting unambiguous state renders the form, total, records and page navigation that the visitor sees.
Variable text is escaped when inserted into HTML. The query in the input value attribute is particularly important. Input resembling an image element consequently remains field content rather than creating an element. The checks exercise exactly that case. This is specific output evidence for this template, not a general security certification for any additional feature that might later be placed around it.
The small experiment deliberately uses no-store so its executed states can be observed directly. It does not investigate cache optimisation. A real public search needs a separate decision about caching, freshness and potentially personal search terms. This example’s setting is neither a recommendation for every result page nor proof of its future scalability. Those decisions require an appropriate deployment and actual requirements.
import {createServer} from 'node:http';
import {readFileSync} from 'node:fs';
import {fileURLToPath} from 'node:url';
import {readQuery, findRecords, queryString} from './search.mjs';
const css = readFileSync(new URL('./example.css',import.meta.url),'utf8');
const escape = value => String(value).replaceAll('&','&').replaceAll('<','<')
.replaceAll('>','>').replaceAll('"','"').replaceAll("'",''');
const shell = body => '<!doctype html><html lang="de"><head><meta charset="utf-8"><meta name="viewport" content="width=device-width,initial-scale=1"><title>Suche im Beispielbestand</title><style>'+css+'</style></head><body><main>'+body+'</main></body></html>';
export function createSearchServer() {
return createServer((req,res) => {
res.setHeader('Content-Type','text/html; charset=utf-8');
res.setHeader('Cache-Control','no-store');
if (req.method !== 'GET') {res.setHeader('Allow','GET');res.writeHead(405);res.end(shell('<h1>Methode nicht unterstützt</h1>'));return;}
const url = new URL(req.url,'http://example.invalid');
if (url.pathname !== '/suche') {res.writeHead(404);res.end(shell('<h1>Nicht gefunden</h1>'));return;}
let result;
try {result = findRecords(readQuery(url.searchParams));}
catch {res.writeHead(400);res.end(shell('<h1>Suchangaben bitte prüfen</h1><p>Suchbegriff, Filter oder Seitenangabe sind ungültig.</p><a href="/suche">Suche zurücksetzen</a>'));return;}
const s=result.state, canonical='/suche'+queryString(s);
if (url.pathname+url.search !== canonical) {res.writeHead(302,{Location:canonical});res.end();return;}
const options=(list,value)=>list.map(([v,t])=>'<option value="'+v+'"'+(v===value?' selected':'')+'>'+t+'</option>').join('');
const form='<form method="get" action="/suche"><label>Suchbegriff<input name="q" value="'+escape(s.q)+'"></label><label>Bereich<select name="category">'+options([['all','Alle'],['web','Webseiten'],['app','Apps'],['ki','KI']],s.category)+'</select></label><label>Sortierung<select name="sort">'+options([['newest','Neueste zuerst'],['title','Titel A bis Z']],s.sort)+'</select></label><button>Suchen</button></form>';
const cards=result.rows.map(row=>'<article data-id="'+row.id+'"><h3>'+escape(row.title)+'</h3><p>'+escape(row.summary)+'</p><small>Fiktiver Eintrag · <time datetime="'+row.date+'">'+row.date.split('-').reverse().join('.')+'</time></small></article>').join('');
const links=Array.from({length:result.pages},(_,i)=>i+1).map(page=>page===s.page?'<span aria-current="page">'+page+'</span>':'<a aria-label="Seite '+page+'" href="/suche'+escape(queryString({...s,page}))+'">'+page+'</a>').join('');
res.writeHead(200);res.end(shell('<h1>Suche im Beispielbestand</h1><p>Zwölf fiktive Einträge für den gezeigten Suchablauf.</p>'+form+'<h2 id="result-title">'+result.total+' Treffer</h2><p id="page-status">Seite '+s.page+' von '+result.pages+'</p>'+ (cards||'<p id="empty">Keine passenden Einträge. Ändern Sie Suchbegriff oder Bereich.</p>')+'<nav aria-label="Ergebnisseiten">'+links+'</nav><a href="/suche">Alle Filter zurücksetzen</a>'));
});
}
if (process.argv[1] && fileURLToPath(import.meta.url) === process.argv[1]) {
const server=createSearchServer();server.listen(0,'127.0.0.1',()=>console.log('http://127.0.0.1:'+server.address().port+'/suche'));
}
Support the same task at narrow widths
The CSS rearranges form controls when less space is available. At very narrow widths they stack vertically. Inputs and selects have comfortably tall surfaces. The visible selection arrow has space from the right edge, and text receives additional room beside it. These details are checked in the rendered interface rather than assumed correct merely because a media query exists in the source file.
Focus indication stays clear. Light and dark appearances use appropriate colours while retaining the same interaction. Browser checks cover widths of 320, 390 and 1440 pixels. The document does not create horizontal page overflow for these cases. That finding concerns the supplied text and fixtures. Later additions containing very long unbreakable strings require renewed review of their actual layout.
*{box-sizing:border-box}body{margin:0;background:#f8f3e9;color:#202428;font:17px/1.5 Arial,sans-serif}main{max-width:70rem;margin:auto;padding:2rem 1.5rem}h1{font-size:2rem;line-height:1.2}form{display:grid;gap:1rem;grid-template-columns:2fr 1fr 1fr auto;align-items:end;padding:1.2rem;border-top:5px solid #cd0712;background:#eee6d9}label{display:grid;gap:.4rem}input,select,button{font:inherit;min-height:48px;border:1px solid #777;border-radius:4px;padding:.65rem;max-width:100%;width:100%}select{appearance:none;background:#fff url("data:image/svg+xml,%3Csvg xmlns='http://www.w3.org/2000/svg' width='12' height='8'%3E%3Cpath d='m1 1 5 5 5-5' fill='none' stroke='%23202428' stroke-width='2'/%3E%3C/svg%3E") no-repeat right 16px center;padding-right:42px}button{background:#cb0712;color:#fff;border-color:#cb0712}article{border-bottom:1px solid #999;padding:.9rem 0}h3{margin:0;font-size:1.2rem}article p{margin:.4rem 0}a{color:#b9000c}:focus-visible{outline:3px solid #cd0712;outline-offset:4px}nav{display:flex;flex-wrap:wrap;gap:.6rem;margin:1.5rem 0}nav a,nav span{min-width:44px;min-height:44px;padding:.55rem 1rem;border:1px solid #777;border-radius:4px;text-align:center}nav [aria-current]{background:#202428;color:white}small{font-size:.85rem}#result-title{scroll-margin-top:1rem}@media(max-width:800px){form{grid-template-columns:1fr 1fr}label:first-child{grid-column:1/-1}}@media(max-width:420px){form{grid-template-columns:1fr}main{padding:1.2rem}h1{font-size:1.7rem}}@media(prefers-color-scheme:dark){body{background:#1e2225;color:#faf3e8}form{background:#30363a}input{background:#fff;color:#202428}a{color:#ff9690}:focus-visible{outline-color:#ff9690}nav [aria-current]{background:#f4eadb;color:#202428}}Exercise the ordinary browser journey
Every tested browser context has JavaScript disabled. The form sends a GET request and pagination uses normal links. A direct address restores the selection from its parameters. After moving to the second result page, the browser Back action restores the first page of that category. The evidence observes the real document and displayed page status, not only an internal state object.
Keyboard interaction begins with Tab entering the labelled query field. Its real focus treatment is checked as well. Production acceptance should also include the intended audience and the assistive technologies they actually use. This automated browser run verifies the described states and input handling. It does not claim comprehensive assessment of every possible supporting technology or unrelated browser-history behaviour outside the executed route.
Loading results dynamically later introduces additional work: loading feedback, failed responses, parallel-response order and understandable result announcements need planning. The previously working URL and link contract remains valuable. An animated update must not lose the selected page or let an older response overwrite a more recent query. Extra convenience should preserve the verified task rather than introduce an incompatible second version.
Understand the 91 executed checks and their scope
The evidence comprises 91 executed conditions using Node 24.22.1 and desktop Edge. Nine direct HTTP requests examine responses and redirects independently of additional browser navigation. The search core is checked for defaults, intersections, Unicode normalisation, literal punctuation, empty selections, bounded pages and deterministic ties. Sorting leaves the original fixture order unchanged, preserving a clean starting point for later requests.
Browser execution includes direct addresses, filter changes, pagination, Back, empty results, reset and suspicious-looking input safely retained as text. Both appearances and several viewport widths are covered. The explanatory image contains actual captures of the running server. On the left is the second page of a category selection. On the right, a new query has moved that selection back to its first page.
This fixed small dataset demonstrates the logic and operation of this template. It does not establish response time under load or suitability of array searching for millions of records. No existing production search belonging to another application was modified. The fictional data keeps reproducible functional evidence separate from unsupported statements about customer information or an already available commercial search offering.
Choose the next architecture from real requirements
With a database, selection still belongs before pagination. Total count and visible slice need the same business filters. Permissions also belong before both computations. Otherwise a list might show only permitted records while its total exposes information from another area. This public fictional collection has no accounts or permission boundaries and does not implement that additional responsibility on behalf of a production application.
Large or frequently changing lists deserve an explicit choice between offsets and cursor-based continuation. A search index also needs an understandable freshness model. An edited description may still have an older version in the index for a period of time. Review these properties with representative data and workloads. Twelve sample records cannot establish credible production capacity, latency or consistency limits.
Start by observing real search tasks: the terms people use, helpful categories and occasions when they reset the selection. Consider data minimisation and the possible personal nature of query text. An unsuccessful search can result from missing content, unfamiliar terminology or excessively restrictive filters. A larger search engine does not automatically solve these different causes, which may need editorial or interaction changes instead.
Plan discoverability for public search addresses deliberately
Many combinable filters can create a very large set of addresses. Google describes possible crawling problems in faceted areas with unnecessary URL combinations. A real collection consequently needs a decision about useful permanent category destinations and arbitrary search states. The fact that our query parameters work correctly does not answer this separate editorial and technical question about which destinations deserve public discovery.
This experiment does not implement a complete search-engine control policy. In particular, application URL normalisation is not treated as a universal canonical policy for all filters. An important category with substantive content differs from an arbitrary empty combination. Actual routes, internal linking and search-engine requirements need coordinated decisions. Treating every variant alike would obscure distinctions important to both visitors and maintenance.
A dependable result list joins clear input meaning, correct selection, stable ordering, understandable pages and a reliable return route. Additional convenience is useful once those foundations agree. The checklist and complete sources provide a concrete way to review an existing workflow and align later extensions with the same verifiable contract, even if the eventual dataset or presentation becomes much larger.
Contract for representative requests
| Case | Outcome |
|---|---|
| No parameters | Twelve results, three per page, newest first |
| Website category | Four records on two pages |
| New query prüfen in website category | One record, page one |
| Valid unmatched query | 200 with empty state |
| Page 99 with four matches | 302 to final available page |
| Page zero or repeated parameter | 400 with reset action |
| Different HTTP method | 405 identifying GET as allowed |
Search and pagination checklist
- Define searched fields and multiple-word semantics explicitly.
- Handle input, allowed values and repeated parameters consistently.
- Filter completely and order deterministically before slicing.
- Derive total and visible records from the same rules.
- Start changed selections on the first page.
- Preserve other values in pagination links.
- Distinguish an invalid request from a valid empty result.
- Encode URL values and escape HTML output for its context.
- Actually exercise direct addresses, Back, reset and keyboard entry.
- Plan database capacity, permissions and search-engine policy separately.
Sources and review scope
Primary sources reviewed on 9 November 2026. Original twelve-record fictional dataset, 91 executed conditions, nine direct HTTP requests and additional real browser navigation. No load measurement or production acceptance is claimed.