Verify caching in the browser and on the server
Sixteen browser fetches and forty-four assertions distinguish fresh responses, no-cache, no-store and a server-side application result.
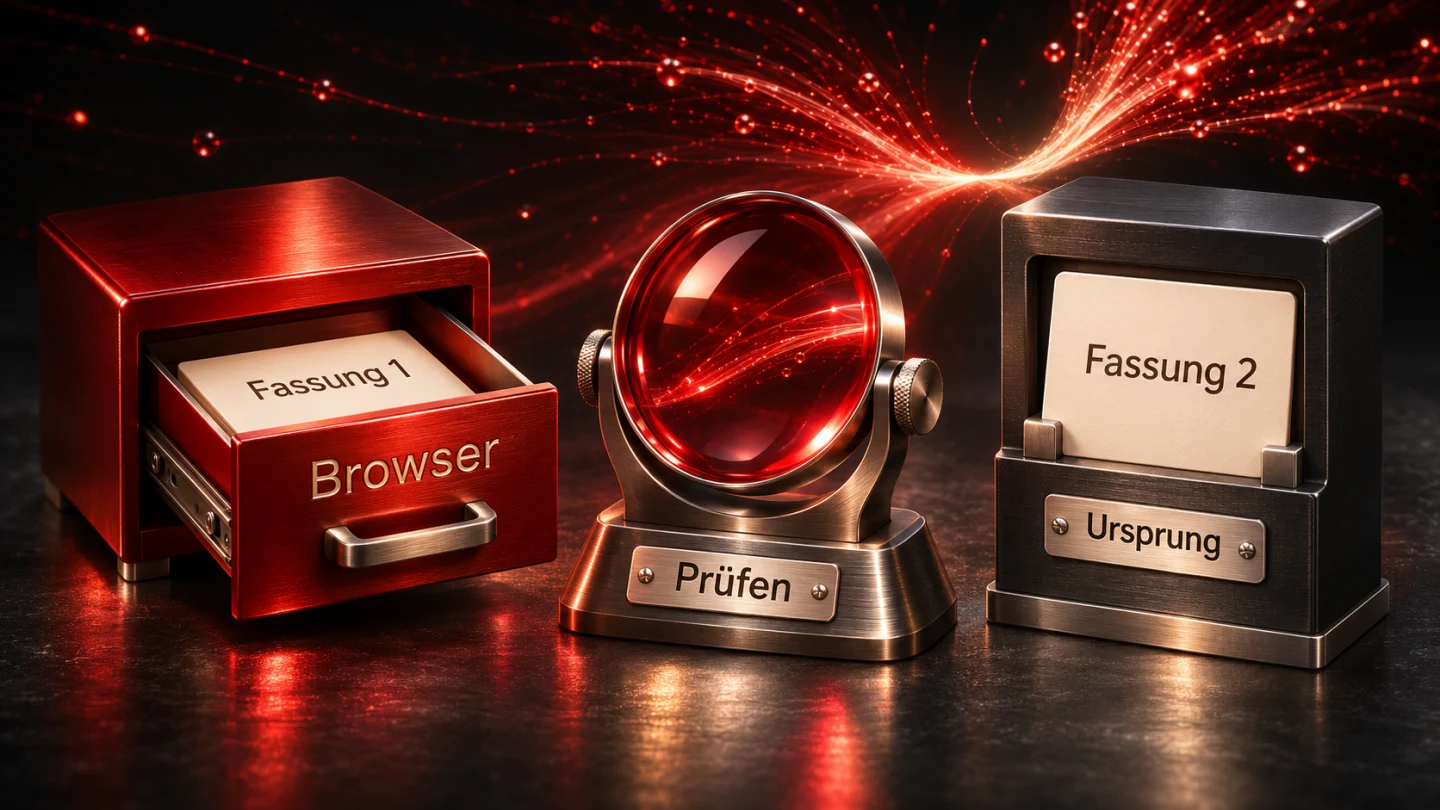
Caching means deliberately reusing a response or a computed result which already exists. Three questions matter: where is the copy stored, under which conditions may it be reused and what makes a change visible? This guide answers those questions with an executed browser experiment using artificial content. The experiment separates fresh browser responses, validation at the origin and an application-owned result stored on the server. It does not measure a customer's page-loading time or claim a universal performance improvement.
Start with a changed piece of editorial content
Our fictional practice text begins at version 1. A page loads it repeatedly and should avoid unnecessary transfers. The editor later publishes version 2. We now care about more than whether the server already possesses the new text. We want to know which version the browser actually receives on its next request. A technically successful response can still contain the earlier version if reuse remains permitted. Whether that is acceptable depends on the freshness requirement agreed for this particular content.
The teaching setup uses an isolated browser context and a loopback server which we control. It has no login, personal information or upstream delivery service. Every version is artificial. The server independently records requests which reach it, allowing us to compare the browser's result with evidence at the origin. That second observation matters. A single status displayed by one tool should not automatically be presented as proof that another complete response body crossed the network.
Keep three storage locations conceptually separate
A browser can retain an HTTP response for its later use. A shared delivery cache can retain responses for multiple visitors. An application can also keep a previously generated result, such as assembled text, in its own storage. These locations have different responsibilities. An outgoing Cache-Control header does not automatically determine how long an application variable retains its value. Clearing that variable does not remove an HTTP response which the browser already has and remains allowed to use.
Only two of these layers actually exist in our experiment: the Edge browser's HTTP cache and a variable in our Node.js process. We do not test a shared proxy or CDN. Adding one later would require its own rules and negative cases. A fast repeated request does not establish that such a service exists. Nor does an outgoing header prove its configuration. Several server workers would also not turn our one-process variable into a consistent shared application cache.
Treat freshness as permission to reuse
In HTTP's model, a fresh response remains within its permitted freshness lifetime. That does not mean nobody could have changed the origin in the meantime. RFC 9111 describes freshness and cache directives. We choose a 600-second lifetime for the experiment's /fresh response and repeat our requests within that interval. We neither wait for a measured ten-minute expiry nor promise that a browser will retain the response throughout that time.
The first actual fetch reaches the origin. The second returns the same content without a further entry in the origin log. That is observed reuse in this particular fresh context. A browser can discard stored responses earlier, so a design should discuss permitted reuse rather than guaranteed storage allocation. For the practice text, the business question remains how long an earlier version may legitimately be shown. That question should be answered before choosing a convenient duration for the response header.
Distinguish no-cache from no-store through the next request
The MDN Cache-Control reference distinguishes these directives explicitly. In simplified terms, no-cache requires successful validation before reuse, while no-store directs HTTP caches not to store the response. private limits storage to private caches. They are not interchangeable additions to an ever-longer precautionary header. A useful policy expresses the intended handling of a particular representation instead of collecting words which sound generally restrictive.
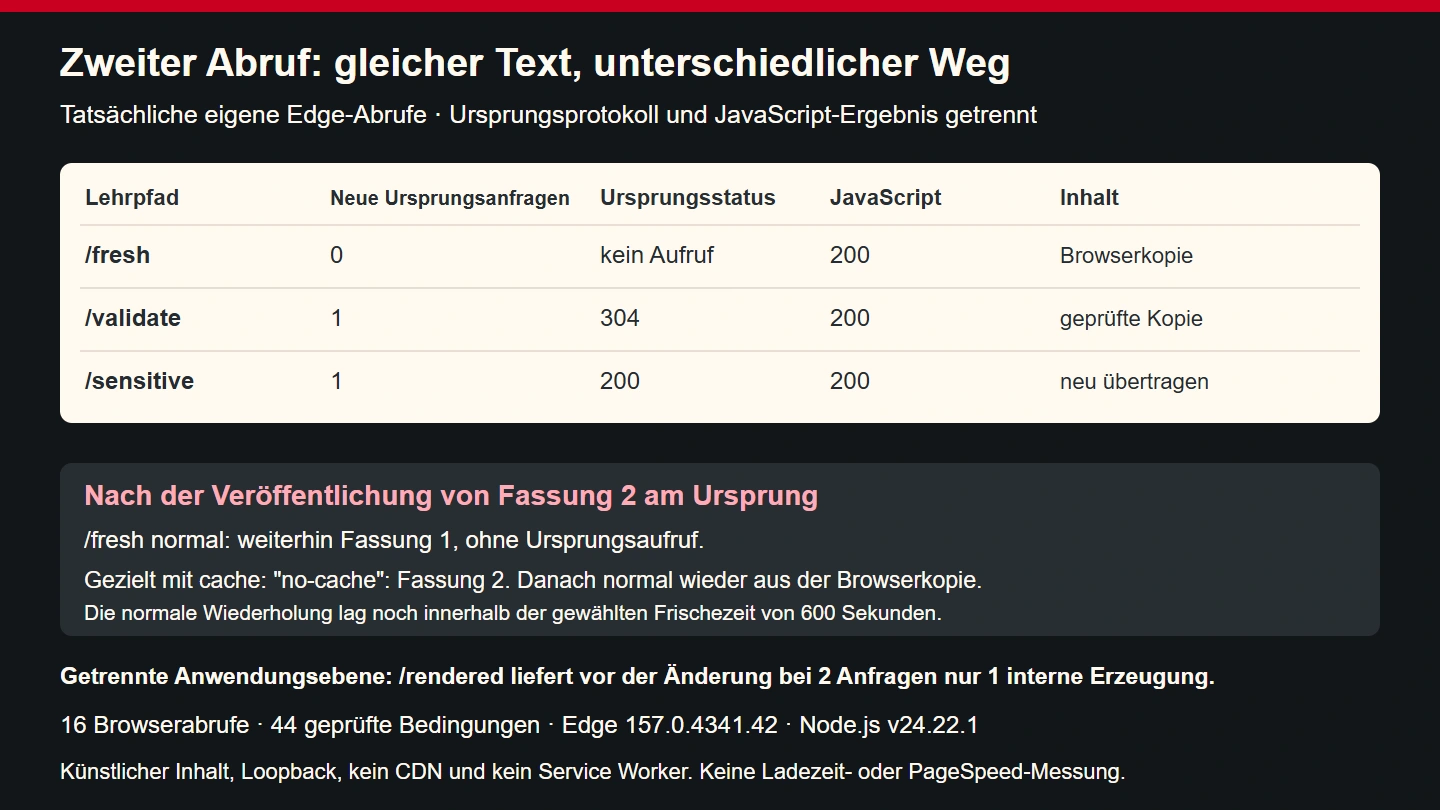
The experiment assigns these policies to separate paths so that we can identify their observed effects. A response from /validate can be reused following validation. A response from /sensitive is not intended to be stored in the HTTP cache. That path name is only a teaching label: its body contains no sensitive information. The name itself creates neither a technical protection nor an evaluated privacy decision. Real personal information would require a separate assessment of the actual application.
| Teaching path | Response policy | Observed second use before publication |
|---|---|---|
| /fresh | public, max-age=600 | No additional origin request |
| /private | private, max-age=600 | No additional origin request in this browser |
| /validate | no-cache | Origin responds with 304 |
| /sensitive | no-store | Another origin request with 200 |
| /rendered | no-store | Another request, internal result reused |
Bind the validator to the representation actually served
An ETag identifies a representation version. The MDN ETag explanation covers its use for unchanged resources. Our own program hashes the exact JSON text which it serves. When the artificial version changes within that text, the identifier changes as well. Generating an unrelated random identifier for every request would defeat recognition of the unchanged text. The generation rule therefore needs to match the representation rather than simply producing something which looks like a version number.
The client treats the identifier as opaque. It does not need to reproduce the hash or infer permission from it. Our observation only needs to establish whether the supplied marker matches the current representation. A checksum does not establish editorial approval. Version 2 can be correctly recognised and still contain a mistake. Responsibility for the content remains distinct from technical identity. Likewise, a representation marker should not be promoted into an authentication secret merely because it appears in a response header.
Follow validation through If-None-Match
When reusing the validation path, the browser submits its existing marker as a condition. For GET and HEAD, the origin can respond with 304 when the representation matches. The header's meaning is described in the If-None-Match reference. Our teaching server implements the matching needed for this experiment. It is not a complete general parser and evaluator of every possible HTTP precondition, and it should not be adopted as if it were such a library.
The actual origin log records zero response-body bytes for that 304. The browser can subsequently use its retained content. The application receives a readable result even though the origin did not send the entire body again. In this observed case, validation avoids another content transfer but still contacts the server. Missing that distinction leads to claims about eliminating requests when the evidence only shows that a repeated response body was unnecessary. The two are useful outcomes, but they are different outcomes.
Understand why JavaScript still receives 200
The browser code receives status 200 on the second fetch of the validation path and can read the JSON body. At the same time, the origin records 304. Those values do not contradict one another. They describe different observation layers. The browser combines its stored response with successful validation, producing a usable response for the application. We therefore retain both observations instead of treating one as an erroneous measurement or rewriting the report to make every status number look identical.
As an independent countercheck, we send the condition directly to the origin using an HTTP client. That request actually receives 304 with empty response text. The countercheck confirms the distinction from the browser-assembled result. It does not mean every frontend should add manual handling for 304 to its ordinary fetch code. The relevant lesson is to identify which layer a diagnostic tool exposes. A clear report distinguishes an application-visible result from the origin's particular wire response.
Do not interpret private as a ban on browser storage
The second fetch of the private teaching path is reusable in the browser we actually tested. The origin sees no second request. That is consistent with explicitly private HTTP storage. It proves nothing about the configuration of a shared delivery service because no such service is present. It also does not establish safe handling of personal information on a shared device. The presence of a cached copy and permission to display it are separate responsibilities which a real application must address.
For an actual user account, we would need to examine logout, account switching and returning to earlier views. A retained HTTP response is not the only possible source of an old interface. Our teaching case does not test those account flows. It uses artificial public text to make one policy observable. A suitable acceptance exercise would inspect the real account view with separate identities and the actual deployment, rather than copying a broad security promise from this small isolated experiment.
Separate no-store from an application-owned copy
The /rendered path also sends no-store. The browser therefore reaches the origin twice in the observed experiment. Yet the application assembles that version's text only once. The resulting string remains in an application variable whose use is controlled by program code, not by the outgoing HTTP header. Two origin requests, two successful HTTP responses and one internal generation can consequently all be true at the same time. The report retains these counts separately because they answer different questions.
This combination is useful when investigating work performed by a system. More origin contacts do not necessarily mean that the same expensive calculation runs every time. Conversely, browser-level reuse can bypass the application altogether. The correct observation point depends on which work the proposed optimisation is meant to avoid. Our counter records calls to the generation point which we defined ourselves. It measures no processor duration, database queries or financial saving in a real editorial platform, and the article makes no such claim.
Trace publication through both layers
The test controller advances the origin from version 1 to version 2 and simultaneously clears the application-owned variable. This is an intentionally modelled publication step, not a public administrative endpoint. We then fetch the fresh browser path again with its normal setting. It still returns version 1 without a new origin request. The origin already has version 2, but the browser does not need to ask it on that request because its previous response remains reusable under the selected policy.
The next deliberately validating fetch obtains version 2. A subsequent normal fetch can reuse that version without another origin request. The validation path behaves differently: its next fetch already contacts the origin and receives the changed body in full. Another repetition returns to a 304 at the origin. This short sequence exposes the publication requirement itself. The desired point at which an editorial change becomes visible must be compatible with every reuse rule on the actual delivery path.
Keep a client option distinct from a response policy
The Fetch option cache: "no-cache" is an instruction from the calling browser code. It is not the same thing as the identically named response directive chosen by the server. The Request cache-property documentation describes the available modes. We use the option narrowly to trigger validation following our artificial publication. We do not present it as a universal setting which should replace the normal behaviour of every fetch in an application.
Forcing every request to bypass its useful stored result could undermine the intended reuse. Appending a random query string to every image address can cause a similar problem. A better plan identifies which particular resource needs immediate freshness and which fixed version can remain unchanged for longer. That decision belongs to the content and its publication process. Client code should support the agreed behaviour without quietly inventing a different delivery rule for every small component or every interaction in the same interface.
Run the complete teaching program
The file uses only built-in Node.js modules. Direct execution binds it to the loopback address and serves a small starting page. The responses contain the same artificial practice text and a version number. The automated experiment starts the exported factory on an available port so that the check does not collide with a fixed address already in use. Publishing this program as a public application service is outside its scope. It contains neither authentication nor durable editorial records.
Save it as cache-demo.mjs and start it with node cache-demo.mjs. The internal publish function exists for controlled test orchestration. It demonstrates separate changes to the application-owned result and the browser's stored response. The starting page does not expose an administration action. A real editorial service would additionally need persistent content, permissions and a reliable publication procedure. This file answers the bounded reuse questions described here; it does not imply that those other responsibilities have been implemented elsewhere.
import{createServer}from'node:http';import{createHash}from'node:crypto';import{pathToFileURL}from'node:url';
export function makeCacheDemo(){
 let version=1,applicationCache=null,renderCount=0;const events=[];
 const policies={'/fresh':'public, max-age=600','/validate':'no-cache','/private':'private, max-age=600','/sensitive':'no-store','/rendered':'no-store'};
 const server=createServer((req,res)=>{
  const path=req.url;
  if(path==='/'){res.writeHead(200,{'Content-Type':'text/html; charset=utf-8','Cache-Control':'no-store'});return res.end('<!doctype html><html lang="de"><meta charset="utf-8"><title>Cache-Lehrversuch</title><h1>Cache-Lehrversuch</h1><p>Kontrollierte eigene Antworten ohne persönliche Daten.</p></html>');}
  if(!Object.hasOwn(policies,path)){res.writeHead(404,{'Cache-Control':'no-store'});return res.end();}
  if(!['GET','HEAD'].includes(req.method)){res.writeHead(405,{'Allow':'GET, HEAD','Cache-Control':'no-store'});return res.end();}
  let body;
  if(path==='/rendered'){
   if(applicationCache===null){renderCount++;applicationCache=JSON.stringify({fassung:version,text:'Eigener künstlicher Praxistext'});}
   body=applicationCache;
  }else body=JSON.stringify({fassung:version,text:'Eigener künstlicher Praxistext'});
  const etag='"'+createHash('sha256').update(body).digest('hex')+'"';
  const headers={'Cache-Control':policies[path],'Content-Type':'application/json; charset=utf-8','ETag':etag};
  const condition=req.headers['if-none-match'];
  const tags=(condition??'').match(/(?:W\/)?"[^\"]*"/g)??[];
  const notModified=condition==='*'||tags.some(tag=>tag.replace(/^W\//,'')===etag);
  // This teaching server supports If-None-Match on GET/HEAD, not all HTTP preconditions.
  if(notModified){events.push({path,status:304,condition,version,body_bytes:0});res.writeHead(304,headers);return res.end();}
  events.push({path,status:200,condition:condition??null,version,body_bytes:req.method==='HEAD'?0:Buffer.byteLength(body)});
  res.writeHead(200,{...headers,'Content-Length':Buffer.byteLength(body)});res.end(req.method==='HEAD'?'':body);
 });
 return {server,events,getRenderCount:()=>renderCount,publish:()=>{version++;applicationCache=null;}};
}
if(process.argv[1]&&import.meta.url===pathToFileURL(process.argv[1]).href){const{server}=makeCacheDemo();server.listen(8788,'127.0.0.1',()=>console.log('http://127.0.0.1:8788'));}
Read the observed results within their limits
The executed experiment contains sixteen browser fetch calls and forty-four assertions. The origin log records fourteen requests to the teaching resources in total, including two separate direct HTTP counterchecks. That count excludes the starting page. The browser was Edge 157.0.4341.42 and the runtime was Node.js 24.22.1. A fresh isolated context ensured that responses from an earlier run were not already present as an uncontrolled starting point. The report retains the actual requests and their response details.
No service worker or CDN participated. We did not measure transfer duration, bandwidth or a PageSpeed score, and we did not wait for the 600-second lifetime to expire. The precise finding is therefore that the documented reuse occurred in these executed, closely spaced requests. Other browsers, different request headers and additional delivery layers need their own checks in the intended deployment. Reporting a smaller number of origin contacts does not justify converting the result into an invented percentage improvement in page speed.
Protect variants from an unsuitable shared key
When additional request headers influence a representation, reuse needs to account for those differences. Vary identifies the relevant headers for HTTP caching. A language-dependent response could otherwise be reused for the wrong language context. Our teaching server does not negotiate language variants, so it reports no completed language-negotiation test. That responsibility becomes concrete when the real interface contract actually introduces such variants rather than merely mentioning them in a configuration example.
An application-owned cache needs an equivalent business-aware key. A label such as homepage may be insufficient if tenant, language and publication version produce different results. The key should represent the differences which genuinely influence output without accumulating unnecessary personal details. Before optimising, list specific counterexamples: which two requests may share one result, and which pairing would return the wrong information? This exercise is usually more revealing than adopting a complicated key format before the underlying distinctions are understood.
Handle fixed assets and changing documents differently
The web.dev HTTP-cache introduction explains reuse through browsers and response headers. A useful planning distinction separates versioned files from documents whose references can change. An unchanged image version can remain reusable at its existing address. The document which points to a new image version needs its own way of making that reference visible. Creating a new filename does not update an earlier document body which the browser is still allowed to reuse without contacting the origin.
A recovery after an incorrect publication also needs to consider versions already delivered. Merely copying an origin file back may not update every retained representation. For the artificial practice text, we would describe which version should appear after recovery and how the necessary validation would happen. That is a planning extension, not a reported production rollback. The current evidence does not claim that an external cache purge or a real customer's recovery procedure was executed as part of this experiment.
Investigate the actual path behind an old view
If earlier content remains visible after an update, first determine what actually ran. An ordinary fetch, a history navigation and an already open application do not necessarily trigger the same work. An interface can also retain its own old text without making another HTTP request. Diagnosis should therefore begin with the request log and the question of whether a request occurred at all. Giving every retained state the same cache label does not establish which component supplied the unexpected content.
Our evidence covers only the explicit fetch sequence. It makes no general claim about the Back button, whole-page restoration or installed-web-application behaviour. This limitation helps transfer the example responsibly: test the previously observed rule against the real flow which needs fixing. A separate source of an old view does not disappear merely because a response header has changed. The relevant acceptance condition is the result of that real flow, not the presence of a particular word in the configuration.
Accept an observable freshness contract
An acceptance exercise should include an initial request, a repetition and changed content. Add the user and language variants which matter in the real service. If a second storage layer exists, verify that clearing or changing it affects the intended output. Independent evidence at the origin or generation point is valuable. It lets the team identify the source of an older version instead of deleting every cache simultaneously and losing the information needed to explain the problem.
- Define each resource's content, change needs and permitted freshness lifetime.
- Name browser, shared HTTP and application-owned storage separately.
- Select no-cache, no-store and private according to their meanings.
- Bind version markers to the representation actually delivered.
- Check initial requests, repetitions and publication with controlled data.
- Distinguish the origin response from the result assembled by the browser.
- Represent relevant language, tenant and permission differences in appropriate keys.
- Include recovery and previously delivered versions in the publication plan.
Good caching produces an understandable freshness contract. A reused response appears for an explicitly permitted reason, and a required change becomes visible through a known route. Our small experiment makes those properties inspectable without turning a count of avoided origin requests into a general promise about loading time, privacy or security. That is the useful foundation for choosing a real policy and verifying that it continues to fit the content as the system changes.